SurferCloud VPS of Asian nodes including Toky
SurferCloud is redefining cloud solutions by offering a...


A GPU hourly rate is not a price — it is one input to a price, and treating the advertised dollars-per-hour as the decision variable is the most expensive habit in GPU procurement. Teams that sort a comparison table by rate and click the cheapest row routinely pay 40 to 80 percent more per finished job than teams that spend one extra hour on arithmetic, because the rate says nothing about how long your workload actually runs on that specific card, what gets metered alongside the GPU, or what happens when the cheap instance disappears mid-epoch.
The redefinition that fixes the comparison: a "GPU server hourly rate" is really a velocity coefficient inside cost-per-unit-of-work — cost per fine-tune, per million tokens served, per thousand rendered frames — and it only becomes a price when multiplied by the hours your job needs on that particular card, plus the storage, egress, idle, and retry line items that never appear in the headline number. Once you compare cost per job, cards stop being "cheap" or "expensive" and start being fast-but-metered or slow-but-flat, which is the only distinction that survives contact with an invoice.
What follows is the working method: the live market bands as of October 2026 from two independent price aggregators; the five structural reasons the identical card sells for three times more two clicks away; the normalization procedure that makes any two listings comparable; a worked fine-tune example in which the rate ordering flattens once real-world factors land; the three (actually four) price planes every provider sells; the line items that quietly exceed the hourly rate; a thirty-minute pre-commitment audit; realistic monthly budgets by workload; and the red flags that tell you a comparison table is about to mislead you.
The direct answer: as of October 2026, real-time aggregators tracking 18-plus providers put floor rates at roughly $0.20 per hour for an RTX 3090, $0.27 for an RTX 4090, $0.27 for an RTX 5090, $0.34 for an A100, $0.60 for an L40S, and $1.41 for an H100 — but every floor is a bait-tier listing, and the honest planning numbers are the second-cheapest available prices, which run one to three times higher.
Two independent aggregators, cross-checked on October 23, 2026, agree on the shape of the market even where they disagree on specific rows. The first, a live pulse tracking 18-plus providers with updates every five minutes, showed H100 at $1.41/hr, A100 at $0.34/hr, RTX 4090 at $0.27/hr, H200 at $1.60/hr, L40S at $0.60/hr, and RTX 3090 at $0.20/hr — alongside a $0.04/hr V100 floor that exists mainly to prove floors cannot be bought. The second, a 2026 dataset covering 500-plus GPU instances across 40-plus providers, shows the dispersion the pulse hides: the same RTX 4090 spans $0.18/hr on a consumer-shared network to $0.69/hr on a premium on-demand platform — a 3.8x spread on one card model.
Here is the conclusion to internalize before reading the table: the dispersion column matters more than the floor column, because dispersion is what your shopping actually encounters, and it is the reason provider selection within a card class matters as much as card selection.
| GPU | VRAM | Floor $/hr (Oct 2026) | Typical available band $/hr | Spread |
|---|---|---|---|---|
| RTX 3090 | 24 GB | $0.20 | $0.215–$0.43 | ~2x |
| RTX 4090 | 24 GB | $0.27 | $0.18–$0.89 | ~4x |
| RTX 5090 | 32 GB | $0.27 | $0.27–$0.36 | ~1.3x (market still forming) |
| A100 | 40–80 GB | $0.34 | $0.40–$1.64 (up to ~$4.50 at premium clouds) | 4x+ |
| L40S | 48 GB | $0.60 | $0.60–$1.67 | ~3x |
| H100 | 80 GB | $1.41 | $1.41–$1.50 at challengers; far higher at hyperscalers | 2–3x |
Two rows deserve a second look. The A100 row is the widest in the table because the name covers two very different products — a 40 GB PCIe card and an 80 GB SXM module — and comparison tables that merge them are comparing a sedan to a truck. The RTX 5090 row is the narrowest because the secondary market for Blackwell consumer silicon is still forming as of October 2026; expect that spread to widen as more suppliers come online.
The direct answer: rate dispersion is structural, not random — it comes from five sources: hardware provenance (peer-shared consumer rigs versus datacenter fleets), region and power economics, priced-in interruption risk, support and SLA layers, and billing granularity with stock games — and you cannot collapse it by "finding the real price," because all five prices are real for different buyers.
The five drivers, in order of how often they surprise people:
The practical consequence: decide which of the five you are buying before comparing rates. A solo developer running checkpointed batch jobs is buying provenance-cheap capacity and should embrace it; a team serving a production endpoint is buying non-interruption and should pay for it rather than pretend the floor is real.
The direct answer: the honest comparison unit is cost per job — hourly rate multiplied by the hours your workload actually needs on that specific card, plus egress, storage, idle time, and a retry factor — and computing it for every candidate takes about ten minutes with one benchmark run and a spreadsheet.
The procedure, step by step:
A note on precision: your first cost-per-job estimate will be wrong by 20 to 30 percent, and that is fine. The method's value is that it is wrong in the same direction for every candidate, so the ranking — which is what you are actually buying — stays stable.
The direct answer: priced end-to-end, a 7B-class LoRA fine-tune that takes 40 hours on an RTX 4090 lands at roughly $14 on a mid-band 4090, about $15 on a cheaper-but-slower RTX 3090, near $30 on a premium-band 4090, and about $41 on an A100 80 GB — the apparent 3.2x rate gap compresses to 2.9x in cost, and the A100 premium only pays for itself when the model outgrows 24 GB of VRAM.
Here is the conclusion before the table: the cheapest rate and the second-cheapest rate produce nearly identical job costs, which means the real decision is between "cheap tier, any vendor" and "premium tier" — not between two vendors inside the cheap tier.
| Listing (Oct 2026 band) | Rate | Est. hours for the job | Retry factor | Compute cost | Extras (storage + egress) | Total |
|---|---|---|---|---|---|---|
| RTX 3090, mid-market | $0.215/hr | 56 h (~40% slower than 4090) | 1.05 | $12.65 | $2.00 | ~$14.65 |
| RTX 4090, low-mid band | $0.30/hr | 40 h | 1.0 | $12.00 | $2.00 | ~$14.00 |
| RTX 4090, premium on-demand | $0.69/hr | 40 h | 1.0 | $27.60 | $2.00 | ~$29.60 |
| A100 80 GB, challenger cloud | $1.29/hr | 30 h | 1.0 | $38.70 | $2.00 | ~$40.70 |
Three takeaways the table earns. First, the $0.215 3090 is a legitimate bargain, not a trap — it loses to the mid-band 4090 by less than a dollar on this job. Second, the premium 4090 at $0.69/hr buys non-interruption and support, not speed; if you need those, pay for them knowingly. Third, the A100's extra $27 buys 56 GB of headroom you do not use on a 7B LoRA — rerun the same table at 30B full fine-tune and the A100 wins outright, because the 24 GB cards simply cannot hold the job.
The direct answer: every provider effectively sells the same card on four price planes — on-demand at full rate, spot or interruptible capacity at 60 to 80 percent off, committed or dedicated capacity at up to roughly 74 percent below on-demand as of October 2026, and fixed-price day or week passes whose effective hourly rate undercuts everything when the pass is fully used — and choosing the right plane usually saves more than choosing the provider.
Here is the conclusion before the table: the planes trade price against interruption risk and commitment, so match the plane to your workload's actual tolerance — not to your optimism about how often you will use the card.
| Plane | Discount vs on-demand | Interruption risk | Commitment | Best for |
|---|---|---|---|---|
| On-demand | — | Low | None | Interactive development, first runs, API-backed serving |
| Spot / interruptible | 60–80% off | High (preemptible, sometimes under 2 hours' notice) | None | Checkpointed training, batch rendering, embedding jobs |
| Committed / dedicated monthly | Up to ~74% off | Lowest | One month or more | 24/7 inference endpoints, known-steady workloads |
| Fixed-price day / week passes | Effective $0.21–$0.25/hr when fully used | Low (per-pass) | Per pass | Burst sprints, evaluation campaigns, scheduled overnight batches |
The plane decision has one dominating rule: spot plus checkpoints beats everything for training. A fine-tune that saves its optimizer state every ten minutes loses at most ten minutes of work to a preemption, so paying full on-demand rates for training is a choice to donate 60 to 80 percent of the budget in exchange for a certainty the checkpoints already provide. The exception is workloads that cannot checkpoint — long single-pass renders with expensive setup, or hyperparameter sweeps where the sweep harness itself is the checkpoint.
The direct answer: on metered platforms, egress, persistent storage, idle interactive time, and retry overhead routinely add 20 to 50 percent to headline compute cost — and on lightly-utilized development instances, idle time alone can exceed the compute, which no rate comparison table will ever show you.
The five line items, ranked by how often they surprise people at invoice time:
The audit move that catches all five at once: run one representative billing cycle — a week, not a month — and compare the invoice total against your naive rate-times-hours estimate. The gap is your organization's true overhead factor; apply it to every future comparison.
The direct answer: for single-node inference of 7B-to-14B models, LoRA fine-tunes up to about 14B parameters, and image or video generation, consumer 24 GB cards at $0.20–$0.40 per hour are the honest rate — the datacenter premium buys 80 GB of VRAM, NVLink-class interconnect, ECC memory, and fleet reliability, none of which those workloads touch.
Here is the conclusion before the table: match the card class to the workload's VRAM ceiling first, then optimize the rate within that class — buying an H100 to serve a quantized 8B model is paying datacenter rent for a consumer workload.
| Workload | Card class that fits | Verdict |
|---|---|---|
| 7B–14B inference, single-digit concurrency | RTX 3090/4090 tier, 24 GB | Consumer tier wins outright |
| 32B at 4-bit, tight context | 24 GB tier or 48 GB L40S | Borderline — benchmark both tiers on your context length |
| 70B serving at 4-bit | 80 GB A100/H100, or dual 24 GB | Datacenter VRAM pays, or dual-consumer gets scrappy |
| LoRA fine-tune, up to ~14B base | 24 GB tier | Consumer tier wins |
| Full fine-tune, 13B and up | A100/H100 80 GB | Datacenter required — VRAM arithmetic, not preference |
| Multi-node distributed training | H100/H200 fleets with interconnect | Not a rate decision at all — a capacity-planning decision |
One caveat keeps the consumer tier honest: consumer cards have no ECC memory, so long unattended training runs carry a small but nonzero risk of a bit flip corrupting a checkpoint. For a 40-hour LoRA run, the standard mitigation is simply keeping two rolling checkpoints — a practice worth having on datacenter cards too.
The direct answer: before committing to any provider, run a standardized half-hour audit — verify the delivered card matches the listing, measure your real workload's throughput, check for thermal throttling, read the interruption and egress policies, and compute effective dollars per unit of work — because listings describe the best case and your job runs in the average case.
The sequence, in order, each step gated on the previous one passing:
nvidia-smi before installing anything: confirm the GPU model and VRAM match what you paid for, the driver is current enough for your runtime, and no other process is squatting on memory. On shared marketplaces this occasionally reveals a listing that flatters its hardware — catch it in minute one, not after a two-hour model download.The whole audit fits inside the first billed hour of a cheap test instance — which is the cheapest due diligence in all of infrastructure procurement.
The direct answer: with October 2026 market rates, a hobby-grade 7B inference endpoint lands around $15–60 per month on the 24 GB tier, a LoRA development cycle around $50–150, occasional batch image generation $10–50 via fixed-price day passes, and a 24/7 production endpoint on 70B-class models $300–800 — and the tier you pick moves the total more than the provider you pick within the tier.
Here is the conclusion before the table: budget by workload pattern, not by card — the same RTX 4090 costs $12 a month for a weekend experimenter and $500 a month for a 24/7 endpoint, and both numbers are correct.
| Workload | Tier | Usage pattern | Realistic monthly cost (Oct 2026) |
|---|---|---|---|
| Personal 7B chat endpoint | RTX 3090/4090, spot or day passes | Evenings and weekends, ~100–200 h | $20–70 |
| Dev/eval fine-tune cycles (7B–14B LoRA) | 24 GB on-demand | 2–4 runs × 30–40 h | $50–150 |
| Scheduled batch image generation | Fixed-price day passes | 2–5 passes per month | $10–50 |
| Production 7B–14B API endpoint, 24/7 | Dedicated 24 GB monthly | 730 h | $170–310 |
| 70B-class serving at 4-bit | A100 80 GB or dual 24 GB | 730 h | $300–800 |
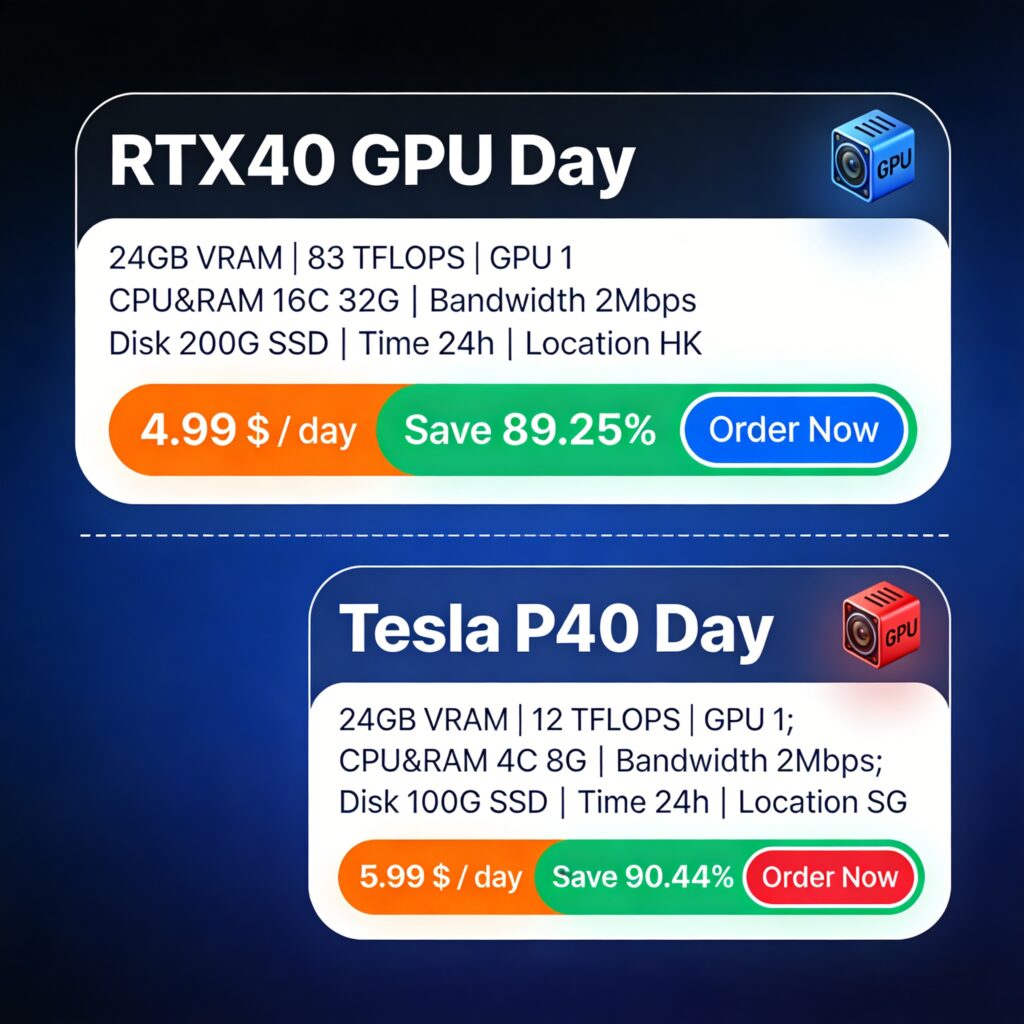
Concrete anchor points for the fixed-price planes, from a live Asia-Pacific promotion checked October 23, 2026: SurferCloud's GPU promotion page lists an RTX 4090-class 24 GB card — 16 vCPU, 32 GB RAM, 200 GB SSD, Hong Kong — at $4.99 for a 24-hour day pass ($0.21/hr effective), $49.99 for a week, and $224.38 per month (about $0.31/hr across a full month), alongside a Singapore Tesla P40 24 GB tier at $5.99 per day and $302.79 per month. Those numbers let a team run the entire plane table above with real arithmetic: the day pass wins for burst sprints, the monthly plan wins somewhere above roughly 45–60 percent utilization. The Hong Kong and Singapore locations matter beyond price for anyone serving users in or around China and Southeast Asia — the regional latency logic is the same one covered in this guide to using Hong Kong servers to reach China and Southeast Asian markets.
One budget line deserves a sanity check before any self-hosting commitment: the API alternative. If your workload is under roughly 20 million tokens a month, calling a hosted model API is frequently cheaper than any GPU rental once idle time is counted — the comparison framework in this developer's guide to the DeepSeek R1 and V3 APIs applies to the break-even math. Self-hosting wins on privacy, ceiling throughput, and cost at scale — not automatically at every scale.
The direct answer: a comparison table will mislead you if it shows no check date, presents floor prices as available prices, merges VRAM variants of one card, ignores egress and idle, or ranks providers by affiliate payout — five flags that disqualify a table faster than any price can qualify it.
The meta-rule: trust tables that show their work — dates, band-versus-floor distinctions, variant labels, and explicit cost model — and distrust tables that merely sort by number.
"Why is the same GPU so much cheaper on one site than another?"
Five structural reasons: peer-shared consumer hardware versus datacenter fleets, regional power costs, priced-in interruption risk, support and SLA layers, and out-of-stock floor listings. All the prices are real — for different buyers with different tolerances. Decide what you are buying before comparing numbers, then compare cost per job, not cost per hour.
"How much does a GPU server cost per hour right now?"
As of October 2026: RTX 3090 (24 GB) about $0.20–0.43/hr; RTX 4090 (24 GB) about $0.27–0.89/hr depending on tier; RTX 5090 (32 GB) from about $0.27/hr while the secondary market forms; A100 $0.40–1.64/hr for rentable listings; L40S (48 GB) $0.60–1.67/hr; H100 (80 GB) from about $1.41/hr at challenger clouds and far more at hyperscalers. Treat any single number without a date and a stock check as decoration.
"Are those $0.18-per-hour RTX 4090 listings real, or a scam?"
Real, not a scam — but they are consumer PCs on peer-sharing networks, not datacenter servers. For checkpointed batch work they are excellent value; for a 24/7 endpoint other people depend on, the reliability premium at $0.34–0.69/hr is usually worth it. Run the thirty-minute audit either way.
"Should I use spot GPUs for training?"
Yes, if and only if you checkpoint. With optimizer state saved every few minutes, a preemption costs minutes of work against a 60–80 percent discount — the best trade in GPU compute. Without checkpoints, spot is a gamble against your longest run, and the expected value flips negative fast.
"How do I compare an hourly rate against a monthly GPU plan?"
Compute your utilization: monthly hours needed divided by 730. Below roughly 45 percent, hourly or day-pass billing wins; above roughly 60 percent, the monthly plan wins. In between, let convenience and the fixed-price predictability decide. As a worked anchor: a $224.38 monthly 24 GB plan breaks even against $0.31/hr of equivalent metered usage — right at the boundary, which is exactly where most small teams live.
"Do I need an H100, or is an RTX 4090 enough for my model?"
For inference of models up to about 32B at 4-bit quantization and LoRA fine-tunes up to about 14B, a 24 GB RTX 4090-class card is enough — and roughly five times cheaper per hour than the H100 floor. The H100 earns its rate for full-parameter training of 13B-plus models, 70B-class serving with headroom, and multi-node work where its interconnect matters.
"Can I trust GPU price comparison websites?"
As inputs, yes; as oracles, no. The live aggregators tracking 18-plus providers with five-minute updates are genuinely useful for seeing the market band — and the two biggest ones disagree on individual rows, which is itself the lesson. Cross-check two, read the date stamps, plan against the available band rather than the floor, and let your own measured cost per unit of work be the final judge.