Google Chrome Remote Desktop Beginner Guide 2
Remote desktop software has become a daily tool for dev...


Self-hosting a large language model is not a model-selection decision — it is a VRAM budget, and every team that gets this wrong gets it wrong in the same direction: they pick the model first, discover the weights do not fit, and then either quantize blindly into garbage output or rent hardware three times larger than the workload needs. The model is the easy part. The budget is the engineering.
The redefinition that makes the problem tractable: "self-hosting an LLM" really means renting or owning just enough VRAM to hold the model's weights, its key-value cache for your context length, and the runtime's activation overhead — with roughly 10 to 20 percent headroom — and then keeping that memory fed fast enough to produce tokens. Once you frame it as a memory-capacity-and-bandwidth problem, the fog clears. The model name becomes a row in a table, the quantization format becomes a multiplier, and the GPU becomes a line item you can price against alternatives instead of a vibe.
What follows is the working playbook: the VRAM arithmetic that decides everything, including the two components people forget; a size table showing exactly what fits on the 24 GB card class that dominates the affordable rental market; the live hourly market prices for that card class as of October 2026; when day-pass and weekly rentals beat monthly commitments for bursty AI workloads; how to choose between llama.cpp, Ollama, and vLLM; the first-hour deployment sequence on a rented GPU server; how to expose the API without getting owned; the monitoring that keeps the bill honest; and the cases where you should not self-host at all.
The direct answer: your VRAM requirement is the model file size, plus the KV cache for your maximum context length and concurrency, plus runtime overhead — and the file size alone is approximately parameters times bytes-per-weight, which turns any model card into a budget line in ten seconds of mental math.
Start with the weights. A model with N billion parameters occupies roughly N × bytes-per-parameter in memory, where the bytes depend on precision: FP16/BF16 is 2 bytes per parameter, INT8 is 1, and 4-bit quantization formats such as GPTQ and AWQ land near 0.5 to 0.6 bytes per parameter after packing and embedding overhead. So the mental math is: a 7–8 billion parameter model at FP16 needs about 14–16 GB just for weights; the same model at 4-bit needs about 4–5 GB. A 70 billion parameter model at 4-bit needs roughly 35–42 GB — which is why 70B does not fit on one 24 GB card no matter what the marketing says, and why dual-GPU setups are the standard 70B answer at the affordable end of the market.
Now the first forgotten component: the KV cache. Every concurrent request stores its attention keys and values in VRAM, and the cache grows linearly with context length. The practical consequence is that "it fits" measured at 2,048 tokens of context can fail at 32,000 tokens with four simultaneous users, even though the weights never moved. The second forgotten component is activation and fragmentation overhead — the runtime pre-allocates workspace, and a budget computed to 100.0 percent of VRAM will OOM on the first batch. A defensible rule: size weights plus KV cache to no more than about 80 to 90 percent of the card, and verify with your real context length, not the demo length. Community measurements from late 2026 put an 8B model at Q4 quantization at roughly 6 GB of actual VRAM in use with full GPU offload, and a 13B model around 10 GB — consistent with the arithmetic above once cache and runtime overhead are added.
Token generation speed, meanwhile, is mostly memory bandwidth: the GPU reads every weight once per generated token, so bandwidth — not FLOPS — sets the ceiling for single-stream inference. This is why a card with 1 TB/s of memory bandwidth embarrasses a card with double the compute but half the bandwidth for chat workloads, and it is the single most useful fact for comparing rental SKUs.
The direct answer: a single 24 GB card comfortably serves 7B–14B models at 4-bit or 8-bit with real concurrency, runs 32B-class models at 4-bit with tight context budgets, and cannot honestly run a 70B model alone — the 24 GB tier is where the price/performance sweet spot for self-hosting lives as of October 2026.
Here is the conclusion to read before the table: the quantization multiplier is doing most of the work in this table, and the context-length row is the one that breaks deployments in week three, not day one. FP16 rows are quality ceilings; the 4-bit rows are the realistic everyday configurations.
| Model class | FP16 (2 B/param) | INT8 (1 B/param) | 4-bit (GPTQ/AWQ/GGUF Q4) | On one 24 GB card |
|---|---|---|---|---|
| 7B–8B (Llama-class, Qwen-class) | ~14–16 GB | ~7–8 GB | ~4–6 GB in use | Comfortable at FP16 weights + moderate context; trivially comfortable quantized with real concurrency |
| 13B–14B | ~26–28 GB | ~13–14 GB | ~7–9 GB in use | Comfortable at INT8/4-bit; FP16 does not fit |
| 32B | ~64 GB | ~32 GB | ~17–20 GB | Fits at 4-bit with a tight context budget; expect to cap concurrency |
| 70B | ~140 GB | ~70 GB | ~38–43 GB | Does not fit on one card — needs 2×24 GB at 4-bit minimum, and the community-standard answer is dual 24 GB or an 80 GB class card |
Two practical notes. First, 12 GB cards (the RTX 3060 class) genuinely run 7B models at 4-bit — if your workload is a personal assistant with one user, the entry tier is real, not aspirational. Second, the "dual 24 GB for 70B" pattern works because inference parallelism across two PCIe-connected cards is bandwidth-limited but adequate for single-digit concurrency; what it cannot do is train. Fine-tuning multiplies memory by optimizer state, and "fine-tune a 70B on two cards" is a fantasy at every quantization level — LoRA on a 7–8B model is the realistic fine-tuning floor for the 24 GB class.
The direct answer: as of October 2026, the live aggregator market shows RTX 4090 24 GB instances from about $0.27 per hour at the absolute floor, $0.34–$0.55 per hour at reputable operators, RTX 3090 24 GB from about $0.20 per hour, A100 80 GB from about $0.34 per hour, and H100 from about $1.41 per hour.
Here is the conclusion before the table: the spread between the floor price and the reputable-operator price for the identical GPU is roughly two to one, and the floor listings are frequently out of stock — so the number that matters for planning is the second-cheapest available price, not the cheapest advertised one. All prices below were checked on October 22, 2026, against a real-time price aggregator tracking 18+ providers.
| GPU | VRAM | Lowest listed $/hr | Typical reputable $/hr | Best fit |
|---|---|---|---|---|
| RTX 3090 | 24 GB | $0.20 | $0.25–$0.40 | Budget inference, experimentation |
| RTX 4090 | 24 GB | $0.27 (out of stock at check) | $0.34–$0.55 (RunPod $0.34, TensorDock $0.35, Lambda $0.50, CoreWeave $0.55) | Production single-node LLM inference, image generation |
| L40S | 48 GB | $0.60 | $0.60–$1.00 | Larger models on one card, video workloads |
| A100 | 80 GB | $0.34 | $1.00–$1.80 | 70B single-card at 4/8-bit, serious fine-tuning |
| H100 | 80 GB | $1.41 | $2.00–$3.50 | Large-scale training, frontier-model serving |
Three observations worth more than the numbers. First, the A100 floor of $0.34/hr is a bait-tier listing that was unavailable at check time — the honest A100 planning number is near $1.00–$1.80, which makes dual-RTX-4090 setups (roughly $0.70–$1.10/hr combined) a legitimate 70B inference alternative. Second, the H100 premium buys training throughput and NVLink-class interconnect, none of which matters for serving a quantized 8B model to fifty users. Third, memory bandwidth varies hugely within "24 GB": the RTX 4090's ~1 TB/s roughly triples the Tesla P40's ~347 GB/s, which is why two cards with identical VRAM can differ by 3–5× in tokens per second on the same model.
The direct answer: if your GPU workload is evaluation runs, scheduled batch generation, overnight embedding jobs, or development bursts — anything under about a hundred hours a month — per-day and weekly rentals are dramatically cheaper than any monthly commitment, and the fixed-price day pass also removes the per-second meter anxiety that makes people rush experiments.
The arithmetic is unforgiving. A monthly plan priced at $224.38 (a current 24 GB RTX 4090-class monthly rate listed on a Hong Kong GPU promotion page, verified October 2026) works out to roughly $0.31 per hour across a full 730-hour month — cheaper than most reputable marketplace hourly rates, and the right answer only if the card works near-continuously. Run the same card eight hours a day, twenty-two days a month, and you consume 176 hours: at $0.34/hr marketplace pricing that is about $60, while the monthly plan still charges the full $224. Utilization below roughly 45 percent, hourly or day-based billing wins; above roughly 60 percent, monthly wins. Between those lines, it is a toss-up and convenience should decide.
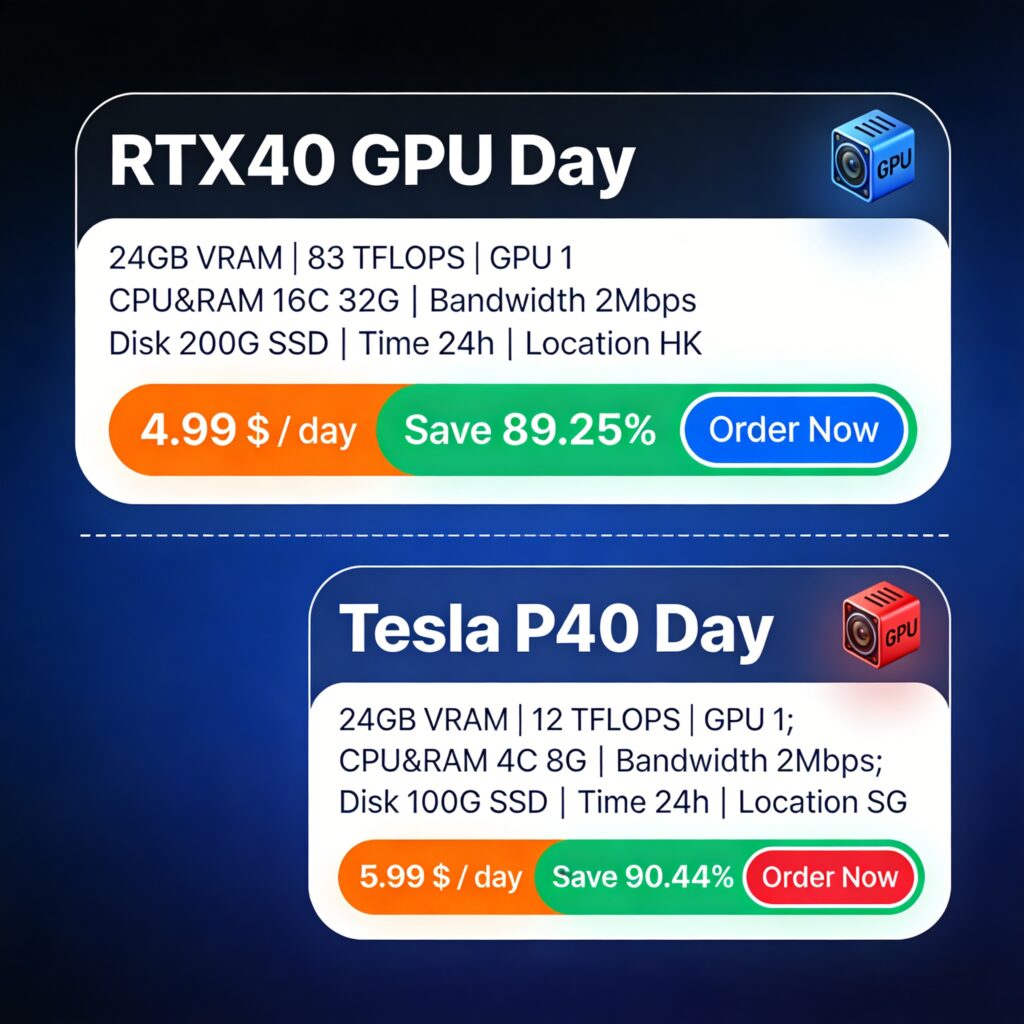
Fixed-price day passes are the underrated middle ground. The same promotion page lists a 24-hour RTX40 pass — one GPU, 16 cores/32 GB RAM, 200 GB SSD, in Hong Kong — at $4.99 per day, which is $0.21 per hour if you use the full window, and effectively free per hour if you run batch jobs around the clock during the pass. A weekly pass at $49.99 covers a week-long evaluation sprint for less than the cost of fifteen metered hours at premium rates. For teams whose AI usage looks like sprints — a new model drops, everyone benchmarks it for three days, then usage collapses — the day-and-week tier is structurally cheaper than everything else. And for serving users in China and Southeast Asia, the Hong Kong location of these SKUs matters as much as the price: latency from Hong Kong into Shenzhen or Singapore beats a cheap US-West card by 150+ milliseconds per round trip, a gap covered in depth in this guide to using Hong Kong servers to reach China and Southeast Asian markets. The same regional logic applies to the promotion's Singapore Tesla P40 tier at $5.99 per day, which trades throughput for a location closer to ASEAN users.
The corollary deserves its own sentence: if you cannot state your monthly GPU-hours from last quarter, you are not ready to commit to a monthly plan, and the honest move is three months of day passes plus a usage log before signing anything.
The direct answer: Ollama is the right choice for single-user and prototype serving, llama.cpp is the right choice when you need maximal control or partial CPU offload, and vLLM is the right choice for any production endpoint with real concurrency — picking the wrong runtime costs you 5–10× in throughput, which no GPU upgrade will paper over.
Here is the conclusion before the table: the runtimes differ less in what models they can run — all three run the popular open-weight families — than in how they behave when the second request arrives while the first is still generating. That is the moment Ollama queues, llama.cpp copes, and vLLM batches.
| Runtime | Concurrency model | Throughput character | Choose when |
|---|---|---|---|
| Ollama | Sequential by default; OLLAMA_NUM_PARALLEL raises the cap but the default is deliberately conservative |
Fine for one user; degrades linearly under parallel load | Personal use, local dev, demos, quick model evaluation |
| llama.cpp | Continuous batching; controllable GPU layer offload (n_gpu_layers) |
Strong single-stream; partial offload trades speed for capacity — CPU-only 7B lands around 8–12 tokens/s in late-2026 community tests | Odd hardware, tight VRAM, GGUF ecosystems, edge cases |
| vLLM | PagedAttention + continuous batching; pre-allocates a configurable VRAM fraction via --gpu-memory-utilization |
Highest aggregate throughput under concurrency; late-2026 community measurements show a 7B model on one RTX 4090 holding 32 concurrent streams steady at 0.9 utilization | Any endpoint other people depend on; OpenAI-compatible APIs |
One integration note saves hours: vLLM ships an OpenAI-compatible server out of the box, which means existing code written against the OpenAI SDK works by changing the base URL — and the same is true of the managed alternatives, which is why the decision framework in this developer's guide to the DeepSeek R1 and V3 APIs applies almost unchanged to self-hosted endpoints. Migrate by swapping base_url, not by rewriting the client.
The direct answer: the first hour on a fresh rental GPU is driver verification, runtime installation, model download, a single-stream smoke test, and a concurrency test at your real context length — in that order, with each step gated on the previous one actually passing.
The sequence:
nvidia-smi before installing anything: confirm the card model matches what you paid for, the driver version is current enough for your CUDA runtime, and no other process is squatting on VRAM. On shared-marketplace vendors this step occasionally reveals a card that is not the one in the listing — catch it in minute one, not after a two-hour model download.--gpu-memory-utilization to leave headroom (0.85–0.90 is the common band), set --max-model-len to your real context requirement rather than the model's maximum, and start with --max-num-seqs conservative. Every OOM in week one traces back to skipping this step.--max-model-len or --max-num-seqs — never "try it and hope."The whole sequence fits in an hour on a fast connection, and every step that feels skippable is the exact step that produces the 2 a.m. incident later. On day passes, run it the moment the instance boots — the pass clock does not care about your meeting schedule. And when the endpoint graduates from a notebook to something other people depend on, the rental tier matters as much as the runtime: as of October 2026, SurferCloud's GPU promotion page lists a 24 GB RTX40-class card — 16 cores and 32 GB RAM, 200 GB SSD, in Hong Kong — at $4.99 for a 24-hour day pass, $49.99 for a week, and $224.38 per month, alongside a Singapore Tesla P40 tier at $5.99 per day: enough span to meter burst workloads by the day and commit by the month once the usage log justifies it.
The direct answer: a self-hosted LLM endpoint must sit behind TLS and an authentication layer from its first minute on the public internet — an OpenAI-compatible server with no auth is an open compute faucet, and scanners find new listening ports within hours, not weeks.
The sequence:
The uncomfortable context: the OpenAI-compatible API shape that makes self-hosted servers convenient is the same shape every exploitation script already speaks. There is no obscurity defense here — assume the endpoint is discovered and probed the day it goes live.
The direct answer: monitor four things — VRAM headroom, tokens per second at known concurrency, queue depth, and GPU-hours burned per day — because the first three predict user-visible failures and the fourth is your actual bill, and all four are visible with tools already on the box.
VRAM is the leading indicator: an endpoint drifting toward 98 percent utilization will serve the next long-context request with an OOM, and the OOM is blamed on the user. Tokens-per-second under a fixed synthetic load is the health baseline — when it drops 30 percent without a config change, something else on the host is eating the machine, which on marketplace vendors is a real phenomenon and grounds for demanding a different node. Queue depth is the capacity truth: rising queues at constant traffic mean you have outgrown the card, not that users got slower.
GPU-hours are the money. Renting per hour makes idle a billable state, so the cron job that stops the instance when no one is using it is the highest-ROI automation on the box — a card burning 24/7 at $0.34/hr costs about $245 a month whether or not a single token is generated. On the host side, plain Linux tooling covers most checks: nvidia-smi for the GPU, and the standard process-level view from this comprehensive guide to checking CPU usage in Linux explains why token generation sometimes starves the CPU-side tokenization and detokenization stages. One number to keep off the dashboard: prompt-engineering experiments. Those belong in notebooks, not on the serving card you are paying by the hour to keep latency-stable.
And when the card lives in Hong Kong or Singapore serving Asian users, add a latency probe from the user side — regional routing quirks (peering congestion, a bad transit path after upstream maintenance) show up as "the AI got slow" with zero server-side symptoms, and only an external probe distinguishes network from model.
The direct answer: do not self-host if your monthly volume is under a few million tokens, if you need frontier-model quality that open weights do not reach, or if you cannot staff the operational burden — a managed API at $5–15 per million output tokens is cheaper than a part-time card plus a part-time engineer in every one of those cases.
The honest ledger has three columns. Managed APIs win on elasticity (zero idle cost), model quality ceiling, and time-to-first-token-of-the-project. Self-hosting wins on per-token cost at sustained high volume, data residency and privacy, fine-tuned-model ownership, and immunity to provider rate limits and deprecations. The middle ground — quantized open models on rented hourly GPUs — wins on burst workloads and experiments. Teams get hurt when they pick a column for identity reasons ("we self-host everything") rather than arithmetic reasons; the arithmetic changes quarterly, so re-run it quarterly.
There is also a hybrid pattern that most teams eventually land on: route the 90 percent of traffic that a 7–14B open model handles fine to your own endpoint, and route the hard tail to a managed frontier API. That pattern gets its cost structure from the self-hosted side and its quality ceiling from the API side, and it is the pattern the VRAM budget in this article exists to serve.
The direct answer, then the questions: the FAQ below covers the sizing, cost, and operations questions people actually type into search boxes and AI assistants, as of October 2026.
How much VRAM do I need to run a 70B model? At 4-bit quantization, roughly 38–43 GB for weights plus KV cache, which means two 24 GB cards at minimum or one 80 GB card comfortably. It does not fit on a single 24 GB card at any usable context length, despite what tool demos suggest.
Is a RTX 4090 enough for LLM inference? Yes — it is the current sweet spot for the 24 GB class: about 1 TB/s of memory bandwidth, and late-2026 community tests show a 7B model serving 32 concurrent streams on one card at high memory utilization. For 70B models, you need two of them at 4-bit, and single-stream speed will be modest because weights split across PCIe.
How much does it cost to self-host an LLM per month? As of October 2026, a 24 GB rental runs roughly $0.27–$0.55 per hour on the market, or about $200–$225 per month on a committed plan; a day pass is about $5. The real answer depends on utilization: a card working 8 hours a day costs about $60/month metered versus $224 committed, so bursty users should rent by the day.
Should I use Ollama or vLLM for a self-hosted API? If only you are calling it, Ollama. If anyone else depends on the endpoint, vLLM — its PagedAttention and continuous batching deliver several-fold higher aggregate throughput under concurrency, and it exposes an OpenAI-compatible API out of the box.
Can I fine-tune a model on a rented 24 GB GPU? You can LoRA-fine-tune 7B–8B models at 4-bit, and that is the realistic ceiling. Full fine-tuning of anything 13B or larger requires optimizer-state memory that dwarfs the card; rent an 80 GB A100-class machine or accept that fine-tuning is a different budget conversation than inference.
Why is my self-hosted LLM so slow compared to the API I was using? Usually one of three things: the model is partially offloaded to system RAM (check nvidia-smi for GPU memory actually used), the runtime is queueing instead of batching (Ollama's default), or your context length is far beyond what you sized the KV cache for. Measure tokens per second at one stream first, then at concurrency — the number that collapses is the diagnosis.
Do I need a GPU in Hong Kong or Singapore for Asian users? If your users are in China or Southeast Asia, yes, it is worth a price premium: round-trip latency from Hong Kong to Shenzhen or Singapore is tens of milliseconds versus 150–250 ms from US West, and LLM sessions feel that gap on every turn. For US/EU users, rent closer to them instead.
Is self-hosting actually cheaper than an API? Past roughly 10–30 million tokens per month of steady volume, yes — the crossover depends on your card's cost per hour and achievable tokens per second. Below that, managed APIs win because your card sits idle and idle VRAM does not refund itself. Log your volume for a month before committing either way.
Remote desktop software has become a daily tool for dev...
Looking to host pre-trained AI models? The right platfo...
Freaky fonts are becoming an essential part of modern d...