How to Run a Cloud Server Trial Properly: A 3
Buying the wrong server is one of the more expensive mi...


An agent loop rarely dies from a wrong answer. It dies from a tool call that never comes back.
That distinction is worth sitting with, because the two failure modes need completely different defences. A wrong answer is a reasoning problem: the model picked a bad step, you can see the bad step in the trace, and you fix the prompt, the tool description, or the guardrail. A stalled call is not a reasoning problem at all. The model is fine. The plan is fine. One of the calls underneath it has simply stopped returning, and because an agent loop is a single sequential path through time, everything behind that call is now frozen.
Ask anyone who has run an agent for more than a few weeks which of the two they have lost more hours to, and the answer is almost always the second. A wrong answer is visible. A missing answer is not.
When a process crashes, the operating system tells you. You get an exit code, a supervisor restart, a line in a log, an alert at 3am. Every piece of machinery you have built for reliability — health checks, restarts, paging — was designed for that signal, and it works.
A hang produces none of it. The process is alive. The event loop is running. Memory is stable and CPU sits near zero, because the agent is not computing anything; it is waiting. Your health check passes, because the health check asks "is the process up?" and the answer is genuinely yes. Your uptime graph is green. And the agent has not completed a step in four hours.
There is a real, well-documented example of this shape in the public issue tracker of a widely deployed agent runtime. In issue #8179, filed 2026-02-03 on macOS, the gateway reported RPC probe: ok while tool calls repeatedly failed with gateway timeout after 10000ms. The reporter's summary of the downstream effect is the part worth remembering: "cron jobs and agent tool calls wedge/abort (e.g., long workflows fail mid-run)." The health probe was fine. The work was not. The two were measuring different things, and only one of them mattered.
That is the whole trap. A hang does not degrade your monitoring; it sits inside the blind spot your monitoring was built around.
The reason hangs are so easy to produce is that the default behaviour of most call mechanisms is to wait indefinitely.
The gRPC documentation states it plainly: "By default, gRPC does not set a deadline which means it is possible for a client to end up waiting for a response effectively forever." The same document's advice is unambiguous — "you should always explicitly set a realistic deadline in your clients." That advice exists because the default is not a safe default.
HTTP clients are no better in the aggregate. It is common for a client to have a connect timeout and no read timeout, or a read timeout inherited from a library default that nobody on the team has ever read. A connect timeout only covers the handshake. Once the socket is open and the peer accepts bytes and then goes quiet, a connection with no read timeout will hold your call open for as long as the network stack allows — which, in practice, is until something else kills it.
And the async primitives are subtler than they look. In Python's asyncio, asyncio.wait() does not cancel anything when it times out — the documentation notes that its futures "continue to run." The same is true of as_completed(): "if a timeout occurs or the iteration is cancelled, the remaining tasks continue to run." These are not bugs. They are the documented contract. But if you assume that adding a timeout to a call means the call stops, you have misread the contract.
Put those three together and the shape of the incident is clear. The agent loop is one sequential control path. Every step awaits the previous step's result. A single await with no ceiling is therefore not a slow step — it is a permanent stop, with the process still reporting healthy.
Here is the mechanism that catches almost everyone. Setting a timeout does not stop the work. It only stops you from waiting for it.
Take the gRPC case. When a client's deadline passes, the client fails the call locally with DEADLINE_EXCEEDED. The server, meanwhile, may still be running the handler. The specification's own guidance acknowledges this and puts the burden on the server author: "the server application is responsible for stopping any activity it has spawned to service the RPC. If your application is running a long-running process you should periodically check if the RPC that initiated it has been cancelled and if so, stop the processing."
Read that as an implementer rather than as a reader: unless your tool cooperatively polls for cancellation, a timed-out call leaves a thread or a task still working on behalf of a caller that has already given up and moved on. The client-side timeout did not reclaim anything. It recycled a waiter.
MCP makes the same point in a different vocabulary. Cancellation in MCP is a notification, not a command. The specification (2026-07-28 revision) says a server receiving a cancellation SHOULD stop processing and free resources — and then adds that a server MAY ignore the notification entirely if the referenced request is unknown, already completed, or, in the specification's own words, "cannot be cancelled." It also warns that "due to network latency, cancellation notifications may arrive after request processing has completed," and keeps the whole mechanism deliberately loose: the error-handling section describes this as maintaining the "fire and forget" nature of notifications.
The same specification is more useful on the timeout question than on the cancellation question, and it is worth quoting because it is one of the few places a protocol says this outright. Implementations "SHOULD establish timeouts for all sent requests, to prevent hung connections and resource exhaustion." They may extend the clock when a progress notification arrives, "as this implies that work is actually happening" — but they "SHOULD always enforce a maximum timeout, regardless of progress notifications, to limit the impact of a misbehaving client or server."
Python's documentation is blunter still. On Task.cancel(): "unlike Future.cancel(), Task.cancel() does not guarantee that the Task will be cancelled." On asyncio.wait_for(), which is what most people reach for as "the timeout": it "cancels aw and raises TimeoutError", but the function "will wait until the future is actually cancelled, so the total wait time may exceed the timeout." And there is asyncio.shield(), whose entire purpose is to make an awaitable refuse cancellation.
So the mental model has to change. A timeout is a decision about your own patience. Cancellation is a request to another party about the work itself. They are two different things, they travel in opposite directions, and only one of them is enforced by the clock.
Now add the reliability layer that everyone adds, and the arithmetic gets uncomfortable.
You set a call timeout because a call might fail. You add retries because a timed-out call is a failed call. And here is what those two reasonable decisions produce together, given the mechanism above.
| Attempt | What your loop sees | What may be true downstream |
|---|---|---|
| Attempt 1 | Times out at 30s, retrying | First invocation still running |
| Attempt 2 | Times out at 30s, retrying | Second invocation still running |
| Attempt 3 | Times out at 30s, retrying | Third invocation still running |
| Attempt 4 | Returns 200 | Four concurrent copies of the same work |
This is retry amplification, and it has a specific and unpleasant property: it fires precisely when the downstream service is already struggling. The service slows down, so calls exceed the timeout, so the caller retries, so the service receives more concurrent requests, so it slows further. The retry policy converted one slow request into four, at the worst possible moment, and every one of those four is doing real work — writing rows, sending messages, charging cards.
The consequence is that a timeout plus a naive retry is a duplicate-side-effect generator. That problem has its own control surface, which is why an at-least-once delivery model needs idempotent actions rather than perfect retry logic. The point here is narrower: retries are only safe on top of a timeout budget, never instead of one.
Most teams respond to their first hang by lowering the timeout. That helps, and it is not enough, because a timeout is a local constant while the deadline is a global quantity.
The distinction is the useful one. A timeout is a duration attached to one call. A deadline is a point in time that belongs to the whole task, and every call in the task should inherit what is left of it. This is what gRPC calls deadline propagation, and the specification solves a problem you will otherwise hit: "since a deadline is set point in time, propagating it as-is to a server can be problematic as the clocks on the two servers might not be synchronized." The fix is that implementations convert the deadline into a timeout with the elapsed time already deducted, which makes the mechanism immune to clock skew.
Practically, that means four things, and they are worth writing down as a contract rather than as configuration:
The last item is the one people skip, and it is the one that makes everything else debuggable. If a tool can only report "error," then a hang, a rejection, and a genuine failure are indistinguishable in your traces, and you will spend the next incident re-deriving what you already knew.
You do not need a new observability stack to catch this. You need one number that most teams already collect and nobody looks at.
Instrument every tool call with its wall-clock duration, then look at the fraction of calls that terminate at the timeout ceiling rather than below it. Call it the ceiling rate. A healthy tool has a distribution with a long, thin tail; a small share of calls approach the limit. A tool with a systemic problem has a distribution that piles up against the limit, because a meaningful share of its calls do not finish at all — they are cut off.
The ceiling rate is more informative than average latency or p99 latency for this specific failure mode, for a simple reason. Averages and percentiles describe calls that completed. A hang is by definition a call that did not, and cutting it off is the only way it enters your data at all. The pile-up at the ceiling is the only place the phenomenon shows up, and it is invisible if you only report averages.
A related signal comes from a recent line of measurement work. GraphACM, posted 2026-10-15, measures behavioural consistency across repeated executions of the same task and finds that the global consistency score predicts task success with an average AUROC of 0.811 across three model families, against 0.729 for the strongest prior behavioural-consistency baseline and 0.769 for asking the model to state its own confidence. The interesting part for anyone running agents in production is not the score itself — it is that a rollout that diverges from its siblings is an early warning. A call that hangs on one run and completes on the next is a divergence, and it is the kind of divergence you can only see if you keep the durations rather than just the outcomes.
Once you start watching the ceiling rate, the temptation is to act on the first explanation that fits. Four explanations fit, and three of them are wrong.
| What you conclude | Why it looks right | What is usually actually happening |
|---|---|---|
| The provider is slow | Every ceiling hit is on a call to the same downstream | Your timeout is tighter than that call's legitimate tail; you are cutting off work that would have finished |
| Nothing is happening, CPU is idle | Load average is flat during the stall | A blocked socket or an unbounded await consumes no CPU by definition; idleness is the symptom, not the absence of a problem |
| The call returned, so the work is done | You got a response and the loop advanced | The response may be an acknowledgement of a queued job, and the acknowledgement arriving does not mean the job finished |
| We sent cancellation, so it stopped | The cancel path ran and logged | Cancellation is a notification that receivers may ignore; the resource may still be held |
There is a fifth lookalike worth separating out, because it is the one that has a research result behind it. It is tempting to assume that a scoring or gating layer downstream will catch whatever a stalled call lets through. "Trust Is Not a Score" (arXiv:2609.39717, v1 2026-09-30, revised 2026-10-16) runs a deterministic failure-injection study over 174 distinct mechanisms in agentic coding and reports that, at the published weights and threshold, a score-only rule admits 56 of 63 injections that the hard gate would block, plus all 24 that the gate would send for review. One of its conclusions is stated almost as an aside and is the most useful sentence in the paper for this discussion: "a missing detector is invisible to every decision rule."
A hang is a missing detector. Nothing errored, so nothing was scored, so nothing was blocked. No amount of downstream aggregation recovers a signal that was never emitted. The paper is explicit that these studies are synthetic and establish neither deployed safety nor cross-domain effectiveness, and that caveat should be repeated whenever the numbers are quoted — but the structural point holds independently of the study: gates can only judge evidence that arrives, and a call that never returns produces none.
Everything above collapses into a short list of obligations. An agent loop is a sequence of steps, and the property you actually want is not "fast" — it is that every step terminates with a reason, so the next step always has something to reason about.
The loop owes four things. A task-level deadline, chosen from the caller's tolerance. A per-call timeout derived from what is left of it, not a constant. A terminal reason on every exit path, distinguishing a timeout from a rejection from a failure. And an accounting of what a timeout may have left running, because that is the quantity your retry policy is about to multiply.
The tool owes two. It should poll for cancellation while doing long work, and it should be safe to run twice. The second obligation is where agent timeouts connect to ordinary distributed-systems practice, and it is the part most teams already have the tooling for.
There is one more obligation that is easy to overlook because it is not code: a long-running agent is a resident process, and a resident process needs somewhere to live that does not sleep. A loop that must enforce a deadline has to be executing in order to notice that the deadline passed. If the machine running it suspends, or the network it depends on is intermittent, or the process is tied to a workstation that gets closed at the end of the day, then the deadline logic is sound and simply never gets the chance to run. That is not a timeout problem. It is a scheduling-surface problem, and it is the reason the slow accumulations that kill a 24/7 agent tend to appear in week three rather than on day one.
The related discipline — deciding which credentials a permanently resident process should hold, given that its tool list is the set of things it can do — is the subject of the credential list as a security boundary. Both concerns get sharper when the agent stops being a process you start and becomes a process that is always there.
Is a shorter timeout always safer? No. A timeout shorter than the tool's legitimate tail converts successful work into retries and duplicates. The goal is a deadline budget that shrinks the tail deliberately, not a number that is small. If the ceiling rate is high, check whether the ceiling is below the working duration before assuming the tool is at fault.
If my client timed out, has the downstream stopped? Not necessarily. A timeout ends your wait; it does not end the remote work. Whether the downstream stops depends on whether it implements cancellation cooperatively, and several protocols only require that it should. Treat every timeout as a possible orphan and make the action safe to repeat.
Do retries make this worse? They multiply it. Each retry is another chance to start a copy of work whose predecessor may still be running. Retries need an idempotency story and a budget, not just a count.
What is the single fastest fix? Put a wall-clock deadline on every tool call that is lower than the loop's own budget, and make the tool return a distinct terminal reason when it is cut off. That alone turns a silent permanent stop into a loop that keeps advancing, and it costs one function wrapper.
The constraint above is what makes a hosted agent a different proposition from a script on a laptop. Enforcing a deadline requires a process that is executing; retrying safely requires a place where a duplicate is cheap to absorb; and running a watchdog alongside the loop requires a host that does not sleep when you close a lid.
That is the case OpenClaw on SurferCloud is built for. The deployment path is a prebuilt image rather than a build: pick the OpenClaw image, add a model API key, and connect the integrations you need — the page lists Slack, Discord, Telegram, Email/SMTP, Webhook and REST API, and GitHub or GitLab among them — in a flow the page describes as about three minutes. Instances run from 1 vCPU / 2GB up to 4 vCPU / 8GB with scaling on demand, in Japan, Singapore, or US data centres, and the page supports OpenAI-compatible endpoints as well as GPT-5, GPT-4, DeepSeek, Claude, Gemini, and GLM, including a custom model endpoint.
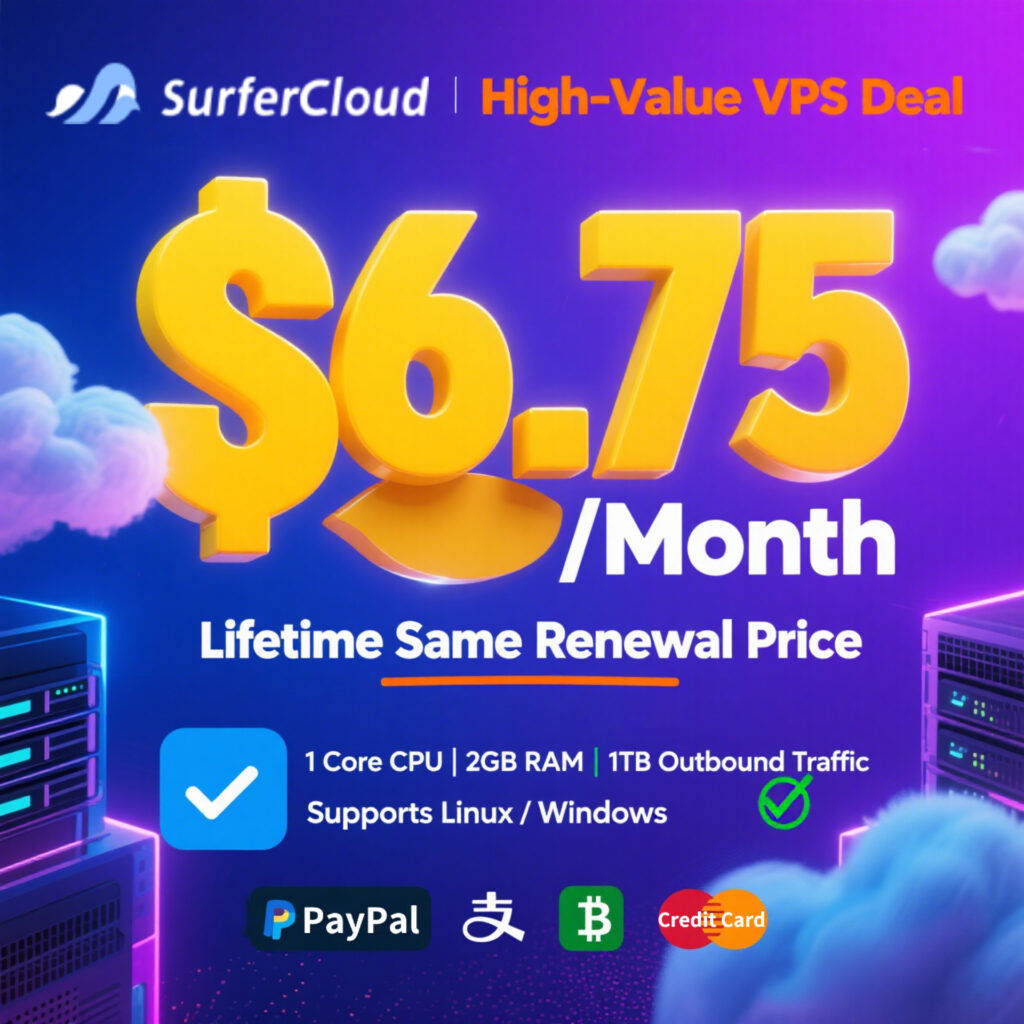
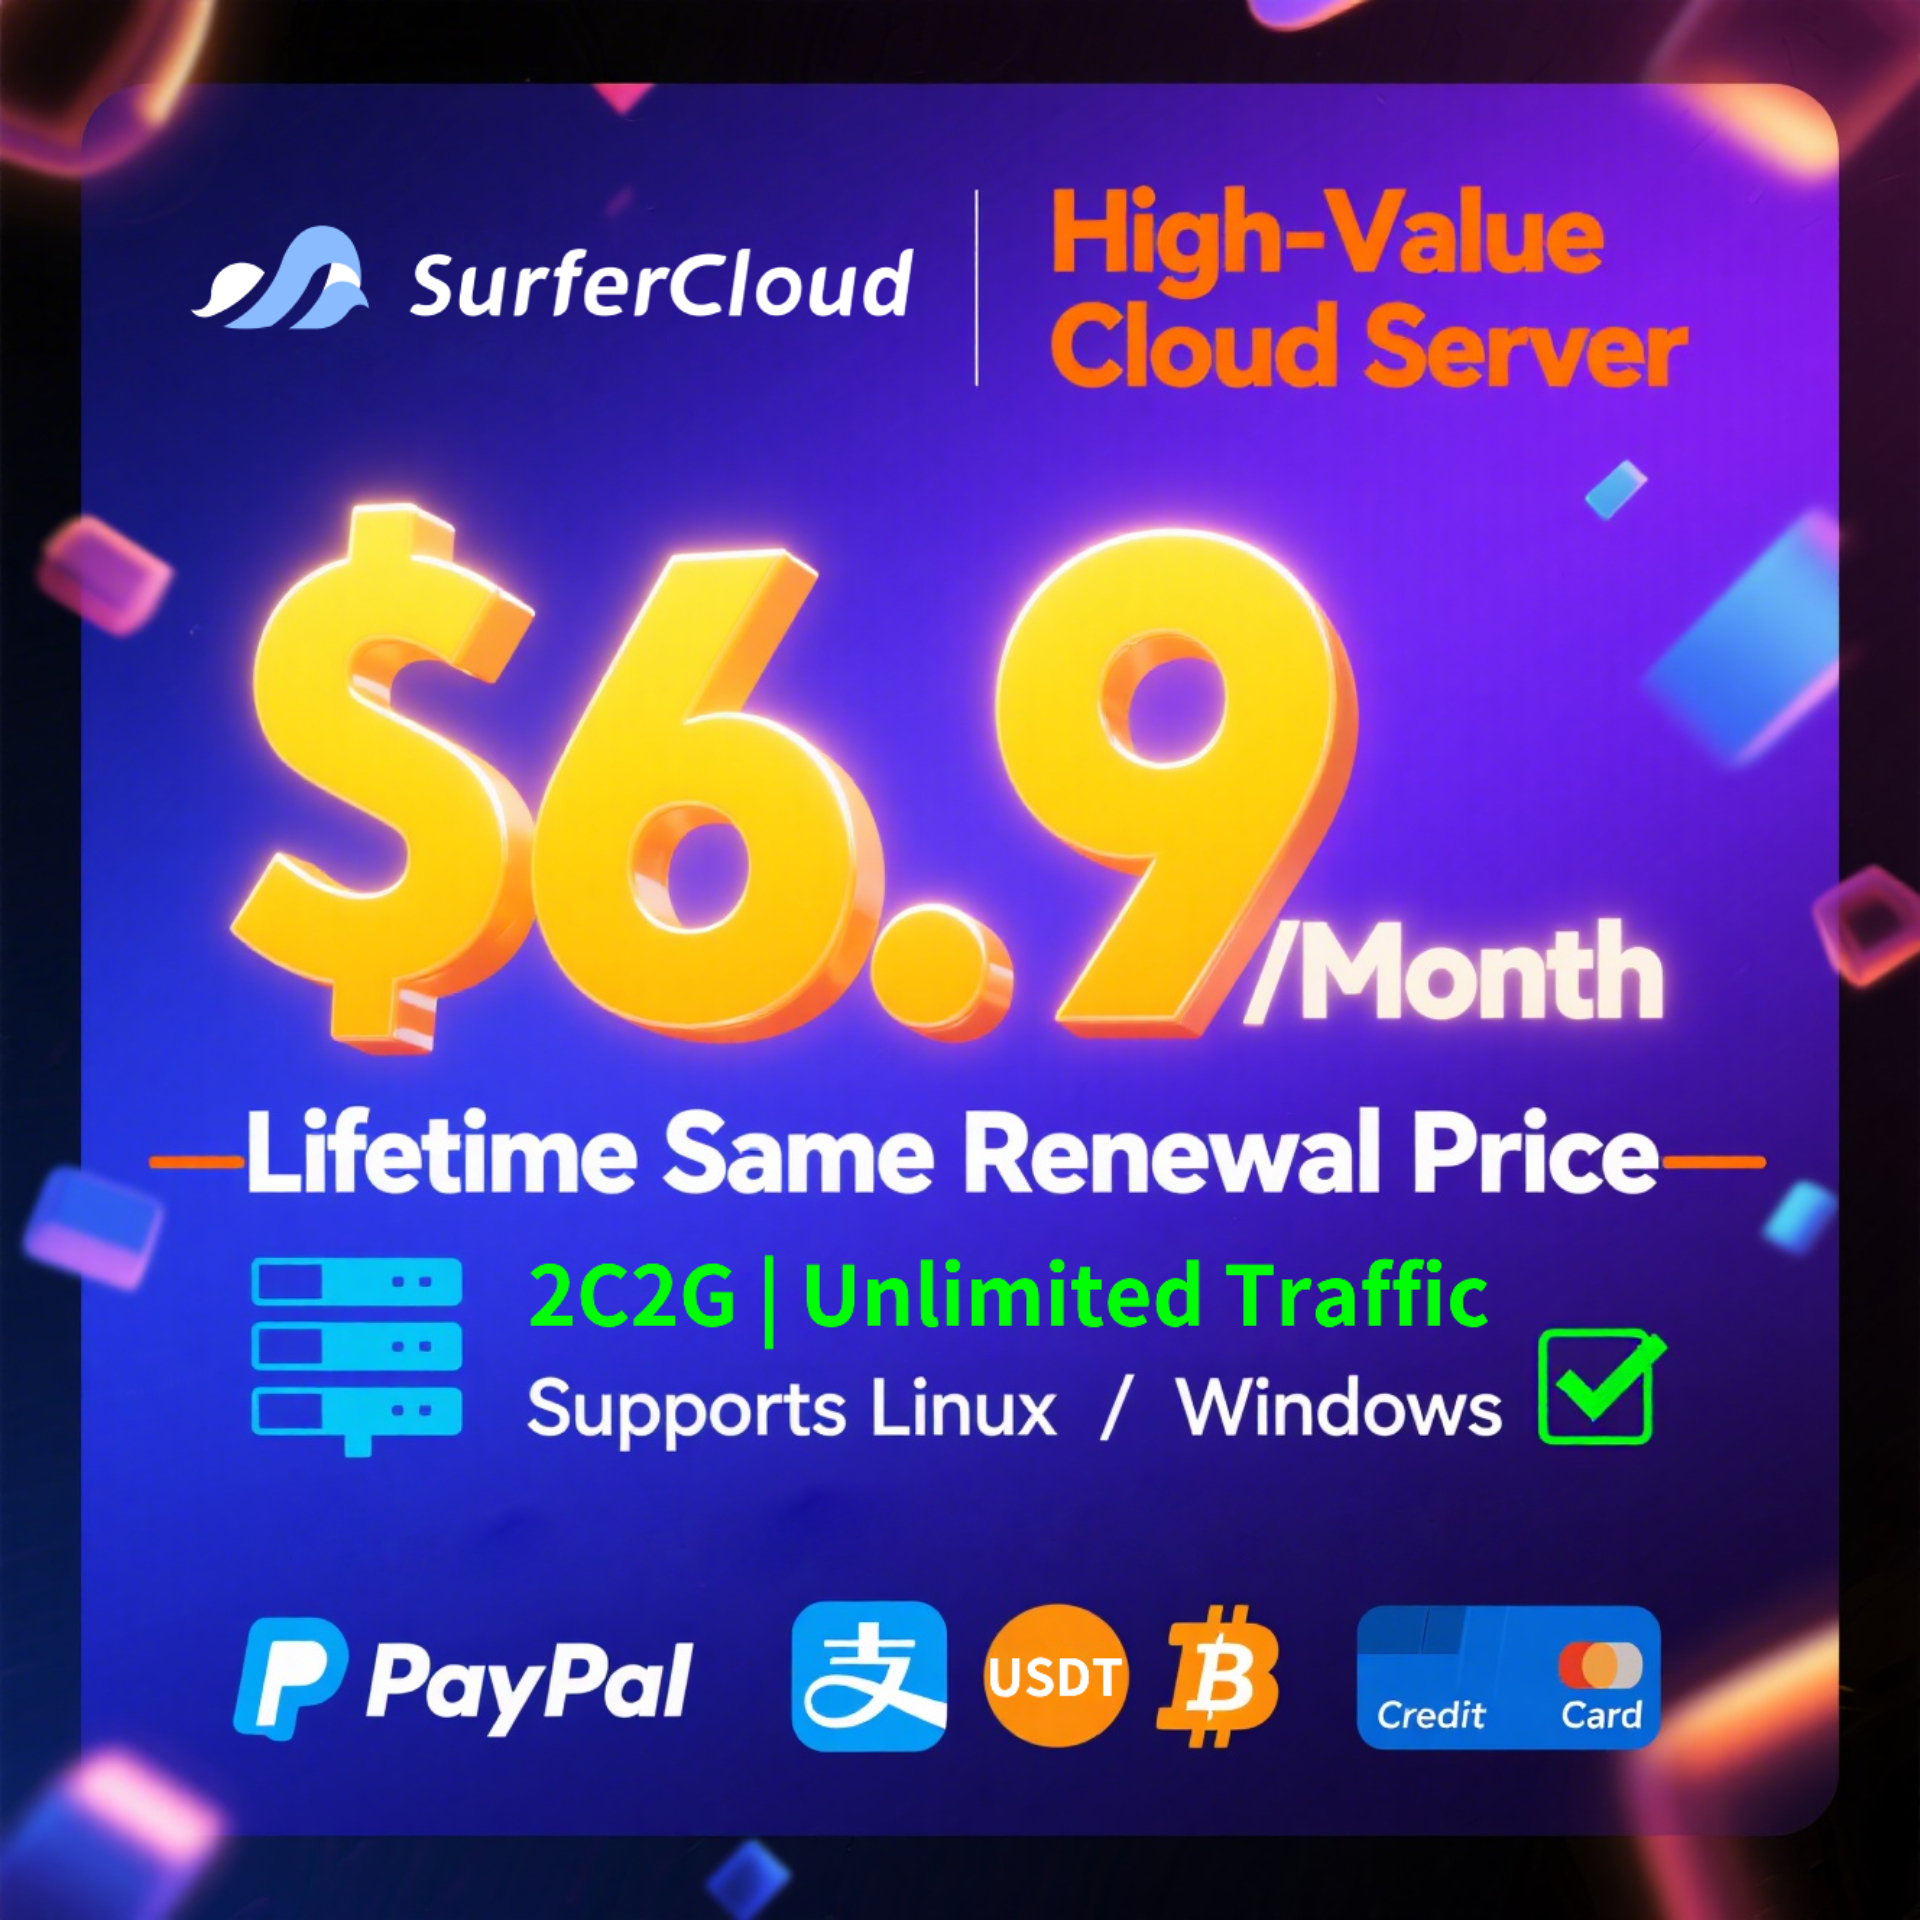
On price, three published configurations are worth knowing. ULightHost monthly fixed pricing lists 1 vCPU / 2GB with a 40GB disk and one IPv4 at 30 Mbps peak bandwidth for $6.75/month, reduced from $7.50. UHost first-month promotional pricing lists 2 vCPU / 2GB with 40GB disk, one IPv4, and dedicated bandwidth for $6.90/month, reduced from $34.16. UHost first-quarter promotional pricing lists 1 vCPU / 2GB at $4.66/month, reduced from $20.49. All three run CentOS Stream 9 64-bit and offer Japan, Singapore, and US data centres. Prices and promotional terms are the page's own and change over time, so confirm them on the page before ordering.
None of this replaces the deadline budget. A host that is always on will faithfully run a loop that has no ceiling, forever, without completing anything. What the host removes is the excuse that the process was not there to enforce the limit.
Deploy an OpenClaw agent on SurferCloud — see current plans and pricing. If you are still deciding whether the workload belongs on a resident host at all, the comparison of always-on cloud deployment against a local machine covers the trade-offs directly.