How to Open Port for ULightHost on SurferClou
Some users have provided feedback that they don't know ...


The RTX 5090 is not a faster 4090, and treating it as one is how teams buy the wrong GPU server: 32 GB of GDDR7, 1,792 GB/s of memory bandwidth, and fifth-generation tensor cores change which workloads are even possible, not merely how fast they run — so the decision is workload triage first, card shopping second. Renting an RTX 5090 cloud server makes sense for a specific, nameable class of jobs; for everything else, the same budget buys more throughput on cheaper silicon, and knowing the difference is worth more than any benchmark chart.
The redefinition that clarifies the decision: an "RTX 5090 GPU cloud server" is really a VRAM-plus-bandwidth envelope with a compute engine attached — the 32 GB capacity determines whether a model fits, the 1,792 GB/s bandwidth determines how fast it serves tokens, and the tensor cores determine training speed — so the card should be selected by the tightest of those three constraints your workload actually hits, not by its position at the top of a price list.
What follows is the working method: the card's real specification as of October 2026 and what each number buys you in practice; the workload classes where the 5090 wins outright and the ones where it quietly wastes money; how the 32 GB VRAM ceiling translates into concrete model fit, quantization, and context-length decisions; where the 5090 sits in the October 2026 rental market alongside a worked monthly cost comparison; how to provision and validate a rental in the first thirty minutes; the reliability and licensing traps specific to flagship consumer silicon; a scaling decision framework for multi-card versus single-card questions; and the seven questions users actually ask before committing.
The direct answer: the RTX 5090 is NVIDIA's Blackwell-architecture flagship consumer GPU — 32 GB of GDDR7 memory on a 512-bit bus delivering 1,792 GB/s of bandwidth, roughly 104.8 TFLOPS of FP32 compute, 680 tensor cores with fourth-generation FP4 support, released January 30, 2025 with a $1,999 launch price — and its defining property for cloud work is that it pairs near-datacenter memory bandwidth with a consumer card's price and power envelope.
Three specification numbers do almost all of the decision work, and each maps to a different workload property. The numbers below are from NVIDIA's published specification pages, current as of October 2026:
| Specification | RTX 5090 | Why it matters for cloud workloads |
|---|---|---|
| VRAM | 32 GB GDDR7 | Determines which models fit on one card — the hard ceiling |
| Memory bandwidth | 1,792 GB/s | Governs tokens-per-second at inference, especially long contexts |
| FP32 compute | ~104.8 TFLOPS | Governs training steps and compute-bound fine-tuning |
| Tensor cores | 680, 5th-gen, FP4-capable | Low-precision inference and training throughput |
| Launch price / date | $1,999 / Jan 30, 2025 | Anchors the rental economics — hardware cost per GB of VRAM |
The 1,792 GB/s bandwidth figure deserves emphasis because it is the number most often ignored and most often decisive. Text generation is a memory-bandwidth-bound workload at inference: every generated token requires streaming model weights through the memory bus, so tokens-per-second tracks bandwidth far more closely than it tracks TFLOPS. The 5090's roughly 78 percent bandwidth advantage over the RTX 4090 (1,792 GB/s versus about 1,008 GB/s) translates directly into serving throughput on large models — and the 32 GB capacity means it can hold models the 4090 cannot fit at all, which is a categorical difference rather than a speed difference. Independent testing through 2026 has repeatedly confirmed the pattern: on vision-language workloads with long inputs and high concurrency, 5090 systems deliver roughly 28 to 30 percent lower end-to-end latency than 48 GB-modified 4090 systems despite the smaller memory, purely on the strength of bandwidth.
The direct answer: the RTX 5090 earns its rental price on five workload classes — quantized 70B-class LLM inference, single-card fine-tuning of 14B–32B models, high-resolution image and video generation, local RAG and long-context serving where 32 GB holds embeddings and model together, and agentic workloads with vision — and outside those five classes, cheaper cards deliver equal or better value.
The five classes, ranked by how decisively the card wins:
Workload-class triage, stated plainly: if your job appears in the list above, the 5090 discussion is about price and provider; if it does not, the discussion should be about a different card. A 24 GB-job runs equally well on a cheaper RTX 4090-class card at a lower rate; a compute-bound training job that fits in 24 GB often runs faster per dollar on multiple cheap cards than on one flagship. The 5090's premium buys capacity and bandwidth — pay it only when your workload consumes both.
The direct answer: the RTX 5090 wastes budget on sub-24 GB inference, small-model fine-tuning, batch jobs that checkpoint and run anywhere, game-streaming or rendering at resolutions a 4090 already handles, and any job whose bottleneck is CPU, RAM, or network rather than GPU memory — because in all five cases you are paying flagship rates for capacity you never touch.
The waste cases, each with its cheaper alternative:
| Workload | Why the 5090 wastes money | Cheaper alternative |
|---|---|---|
| 7B–13B model inference (4/8-bit) | Fits comfortably in 24 GB; bandwidth advantage barely used at short contexts | RTX 4090 / RTX 3090 class card at a lower hourly rate |
| 7B model full fine-tuning | Compute-bound, fits in 24 GB — flagship capacity idle | 4090-class card, or a multi-card 3090 rig for throughput |
| Scheduled batch jobs (nightly summaries, bulk embeddings) | Checkpointable, latency-insensitive — provenance-cheap capacity wins | Interruptible / spot-style capacity on prior-generation silicon |
| 1080p game streaming and sub-4K rendering | A 4090 already saturates these; the 5090 premium buys headroom nothing uses | 4090 or lower; spend the savings on NVMe |
| Web scraping and API aggregation for AI agents | Bottleneck is CPU, RAM, and egress — GPU is decorative | A lightweight cloud server with enough RAM; no GPU at all |
The last row deserves a paragraph of its own because it is the most common mispurchase in AI-agent infrastructure. Agent frameworks are usually sold with GPU imagery, but a typical agent loop spends its wall-clock time in HTTP requests, JSON parsing, and long sleeps between scheduled runs — work that a lightweight cloud server with a modest CPU and a few GB of RAM handles for a few dollars a month. If you are running that class of workload, the GPU server decision is not "which GPU" but "whether GPU," and the answer is usually no. The same logic extends to any 24-GB-fitting job: the step down in rate is always larger than the step down in throughput.
The direct answer: on a single 32 GB card as of October 2026 you can run 8B–14B models at FP16 or 8-bit with generous contexts, 32B models at 4-bit quantization with full fine-tuning headroom via QLoRA, and 70B models only at aggressive 3-bit-class quantization with short contexts — and each of those three tiers corresponds to a genuinely different product decision rather than a settings tweak.
The fit table, with the numbers that actually drive the decisions. Capacity figures are the practical working set — weights plus KV-cache plus working memory — not the theoretical weight-file size, because KV-cache growth with context length is the line item that surprises people:
| Model class | Precision | Approx. VRAM working set | Fits 32 GB? | Notes |
|---|---|---|---|---|
| 8B (Llama-class) | FP16 | ~17–20 GB with context | Yes, with long contexts | The workhorse tier; even 128K contexts fit |
| 14B | 8-bit | ~12–15 GB | Yes, easily | Best quality-per-GB on the card |
| 32B (Qwen-class dense) | 4-bit | ~20–24 GB | Yes, QLoRA fine-tuning viable | The card's signature capability |
| 32B | 8-bit | ~34–38 GB | No | Requires 48 GB cards or 2-GPU split |
| 70B | 4-bit | ~38–42 GB | No | Does not fit; needs dual 32 GB or 48 GB |
| 70B | 3-bit / hybrid | ~28–31 GB | Marginally, short contexts | Demonstrated in community testing, not production-grade |
Two decisions hide inside this table. First, the KV-cache tax: attention key-value memory grows linearly (for most architectures) with context length, and at 262K-class vision-context lengths the cache alone can consume 8 to 12 GB — which is why a model that "fits" on paper pages and stalls in practice when context fills. If your application serves long documents or agentic histories, budget the cache as a first-class line item, not an afterthought. Second, the quantization cliff: dropping from 8-bit to 4-bit roughly halves the working set at a quality cost that is usually acceptable for serving but detectable in fine-tuning — so the right question is never "does 32B fit" but "does 32B at the precision my quality bar requires fit," and the answer changes the card.
The direct answer: as of October 2026, RTX 5090 cloud rental rates run from roughly $0.27 per hour at peer-sharing marketplaces to $0.39 and above on datacenter-grade platforms, with availability described as high and improving — and the same dispersion rules that govern all GPU pricing apply: the floor is not the price, and planning numbers should come from the band.
The market context, from listings checked in October 2026. One major peer-to-peer GPU marketplace lists RTX 5090 instances from $0.37–$0.39 per hour with high availability, alongside 2026 dataset coverage showing the same card at $0.27–$0.36 across a 500-plus-instance provider census; a separate October 2026 survey of seventeen mostly-Asia-facing platforms found per-card-hour rates equivalent to roughly $0.38–$0.57. The consistent picture across sources: the 5090 rents at a 20 to 40 percent premium over the RTX 4090's typical band, at roughly one-third of A100 pricing, with the spread still narrow because the secondary market for Blackwell consumer silicon is still forming.
| Card | VRAM | Rental band $/hr (Oct 2026) | Positioning versus the 5090 |
|---|---|---|---|
| RTX 3090 | 24 GB | $0.20–$0.43 | Cheapest 24 GB; half the bandwidth |
| RTX 4090 | 24 GB | $0.18–$0.89 | Same capacity, ~45% less bandwidth; the value baseline |
| RTX 5090 | 32 GB | $0.27–$0.57 | Reference row: the 32 GB bandwidth flagship |
| A100 (40 GB) | 40 GB | $0.40–$1.64 | More VRAM, similar or higher rates; datacenter pedigree |
| H100 | 80 GB | $1.41+ | Different universe of budget and throughput |
The honest read of the market: the 5090's price premium over the 4090 is 20 to 40 percent, and its bandwidth advantage is roughly 78 percent — meaning on any workload that is bandwidth-bound (which inference is), the 5090 delivers more tokens per rental dollar than the 4090 whenever the model fits in both cards. The crossover is capacity: jobs that fit in 24 GB should price both cards and compute cost per job; jobs that need 25–32 GB have no crossover to compute, because only one card can run them.
The direct answer: for a representative always-on 32B-model inference workload, a single RTX 5090 at $0.39 per hour costs roughly $285 per month all-in and beats both the dual-4090 alternative (which cannot hold the model in 48 GB of split memory without complexity) and the A100 alternative (which costs 2 to 4 times more) — while a 24 GB-class workload flips the table and prefers the cheaper cards.
The worked example, with every assumption stated. Workload: one 32B dense model at 4-bit, serving interactive traffic 24/7, requiring the full working set resident (no offload). Monthly cost = hourly rate × 730 hours, rounded, as of October 2026 market rates:
| Option | Effective rate | Monthly (730 hr) | Runs 32B @ 4-bit resident? | Verdict |
|---|---|---|---|---|
| 1× RTX 5090 (32 GB) | $0.39/hr | ~$285 | Yes — 20–24 GB fits with headroom | Winner for this class |
| 1× RTX 4090 (24 GB) | $0.34/hr | ~$248 | No — does not fit | Cannot serve the workload |
| 2× RTX 4090 (split) | $0.68/hr | ~$496 | Yes, via tensor-split | Costs more and adds failure modes |
| 1× A100 (40 GB) | $0.89/hr | ~$650 | Yes | 2.3× the winner's cost |
Now flip the workload and watch the verdict invert. Serve a 7B model at 8-bit instead — roughly 9 GB of working set, fits every card in the table — and the 5090's $285 becomes the 4090's $248 with near-identical serving throughput, because a small model at moderate contexts is not bandwidth-saturated. The lesson generalizes: the worked table is not an argument for the 5090, it is an argument for running the table — your workload's working set and bandwidth saturation decide each row, and they decide it differently for every model class.
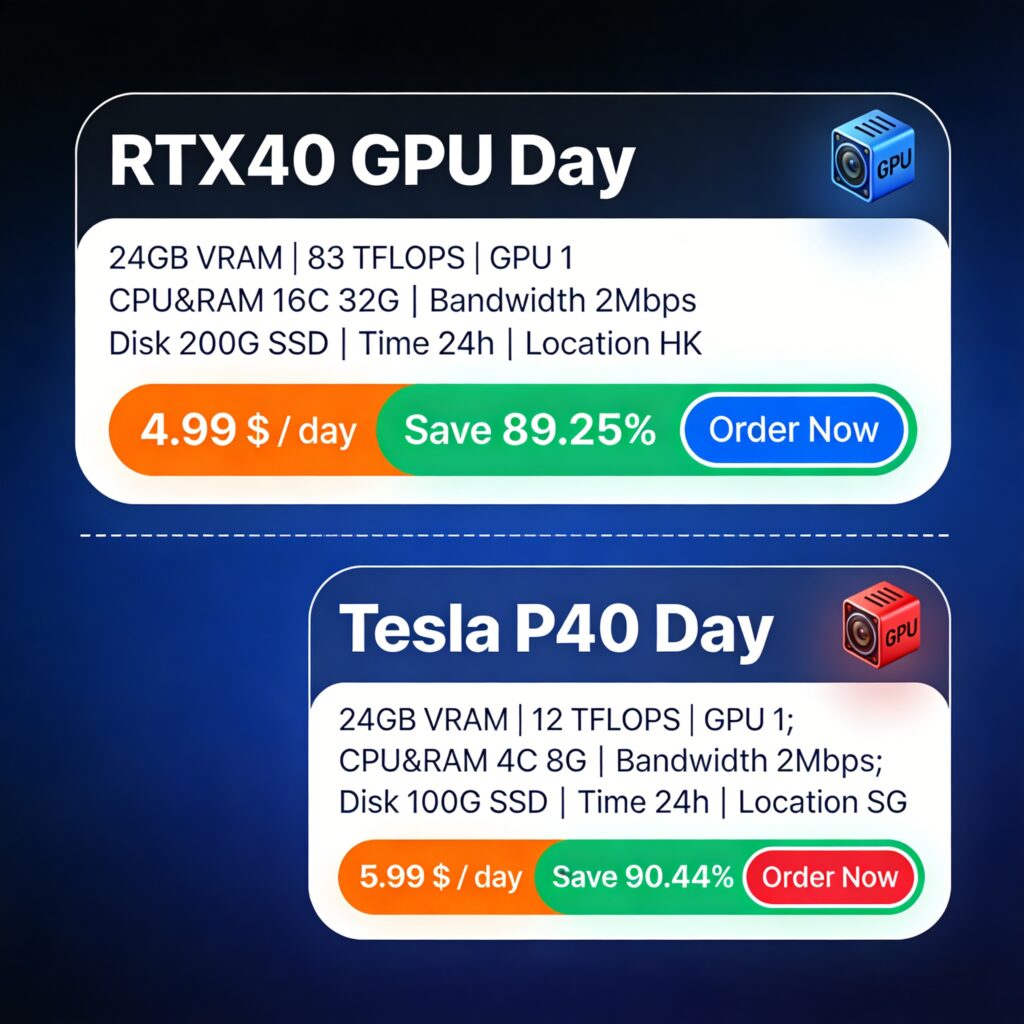
One scheduling note for readers comparing committed structures: SurferCloud's GPU promotions page lists RTX 40-class and Tesla P40 plans — such as an RTX40 24 GB instance at $4.99 per day or $224.38 per month in Hong Kong and a Tesla P40 24 GB at $5.99 per day in Singapore, as of October 2026 — alongside an RTX 5090 rollout in its US region that the promotions page tracks. For 24 GB-class jobs, day-pass structures like that are frequently the cheapest committed form per calendar month; for 32 GB-class jobs, the 5090 bands above are the market until more of that stock lands — and if your users are in or near Southeast Asia, Hong Kong hosting's latency advantages for reaching China and Southeast Asia are worth pricing into the region choice before you commit.
The direct answer: in the first thirty minutes on any rented RTX 5090 you should verify the card is what you paid for, install a matching CUDA stack, run one bandwidth test, and load your actual model once — because silent misconfiguration (wrong card, mismatched drivers, thermal throttling) is more common than hardware failure and costs the same rental hours.
The checklist, in the order it should be executed:
nvidia-smi and confirm the card reads "RTX 5090" with 32,768 MiB (roughly 32,763 reported) of memory. Mislabeled or substituted cards are rare but real on peer marketplaces; thirty seconds here prevents a month of degraded runs.nvidia-smi dmon or the telemetry panel: clocks should hold near boost, temperatures below 80°C, and "Perf" at P0. A card stuck at P2 or throttling at 65°C is a host problem — open a ticket before burning more hours. The same discipline applies to any rented server: knowing how to read CPU usage on Linux catches host-side contention that masquerades as GPU slowness.Step five is the one that saves careers: it converts the capacity tables from marketing claims into measured fact for your specific stack — quantization format, context length, attention implementation — all of which shift the working set by gigabytes. Do it once, on every new card class, before you trust any planning number again.
The direct answer: renting flagship consumer GPUs carries three traps that datacenter cards do not — peer-marketplace provenance risk (the card may be a gaming rig with consumer cooling), driver and licensing restrictions in some datacenter regions (consumer GeForce cards are not licensed for datacenter deployment in every jurisdiction and some providers accordingly cap features), and thermal consistency under sustained load (575 W sustained heat is a cooling problem that hosts solve unevenly) — and all three are checkable before you commit budget.
The traps and their checks, briefly:
None of these traps is a reason to avoid the 5090; they are reasons to buy it from a counterparty whose incentives you understand. A flagged-but-verified host on a day-pass rate is a legitimate choice for a weekend experiment; the same card on a monthly commitment deserves the thirty-minute audit from the previous section plus a support channel that answers in hours, not forum threads. And if the audit keeps failing across providers, the fallback for many 24 GB-class jobs is prior-generation silicon — the same cost-effectiveness reasoning that makes NAT VPS hosting viable for CPU work applies to last-generation GPUs: last year's flagship at a discount serves every workload that fits in its smaller envelope.
The direct answer: choose a single 5090 when your model fits in 32 GB and you value simplicity, deterministic latency, and single-card debugging; choose multi-card cheaper silicon when you need more aggregate VRAM than 32 GB for training, when your throughput scales cleanly across shards, or when interruptible spot-style capacity can be checkpoint-restarted — and never split a model across cards to save money on serving, because the split costs more than it saves.
The decision, as a pair of rules with their exceptions:
The scaling decision is thus usually a capacity decision wearing a throughput costume. Teams believe they need two cards for speed; measurement usually shows they needed 6 more GB of VRAM, or 400 more GB/s of bandwidth, or nothing at all. Buy the constraint you actually hit.
The direct answer: the questions below are the ones buyers actually ask — phrased the way they ask them — and each answer states its bottom line in the first sentence, with the reasoning following.
Can an RTX 5090 run a 70B model?
Only at aggressive quantization. A 70B model at 4-bit needs roughly 38 to 42 GB, which exceeds 32 GB; 3-bit and hybrid quantizations bring it to roughly 28 to 31 GB and community testing has demonstrated interactive use, but with real quality loss and short-context constraints. Treat single-card 70B on a 5090 as an experimental capability, not a production plan; the honest single-card ceiling for daily work is the 32B class at 4-bit.
Is the RTX 5090 worth it over the RTX 4090 for LLM inference?
Only when the model needs more than 24 GB. Below 24 GB, the two cards serve a given model with similar throughput and the 4090's lower rate wins; above it, the comparison ends because the 4090 cannot load the model. Within the overlap, the 5090's ~78 percent bandwidth advantage shows up mainly at long contexts and high concurrency, where real tests show roughly 28 to 30 percent better latency — real, but worth 20 to 40 percent more per hour only for long-context, high-concurrency serving.
How much VRAM do I actually get on a rented 5090?
32 GB in full: the card reports 32,768 MiB, and unlike some virtualized datacenter offerings there is no partitioning on standard rental instances — but verify with nvidia-smi in your first minutes, because the only way to know what a specific provider gives you is to look.
What's the cheapest way to run a 32B model 24/7?
A single RTX 5090 at the low end of the October 2026 band, roughly $0.27–$0.39 per hour or about $200–$285 per month for always-on, is the cheapest resident structure for 32B-at-4-bit — cheaper than dual 4090s, and roughly a third of A100 pricing. If your traffic is bursty rather than always-on, day-pass or scale-to-zero structures can cut it further, at the cost of cold-start latency.
Can I fine-tune a 32B model on one 5090?
Yes — QLoRA at 4-bit is the designed answer: roughly 20 to 24 GB of working set covers weights, adapters, and activations with headroom on 32 GB. Full-parameter fine-tuning at higher precision does not fit and needs multi-card; but adapter-based customization, which is what most teams actually need, is the card's home turf.
Do I need a GPU server at all for my AI agent?
Probably not, if the agent calls hosted model APIs and spends its time in HTTP requests, parsing, and scheduled sleeps. That workload is CPU-and-RAM bound, and a lightweight cloud server at a few dollars a month serves it identically — the GPU decision belongs to the teams self-hosting models, which is the decision this entire article addresses.
Will RTX 5090 rental prices drop soon?
History says yes, directionally: flagship consumer cards enter the rental market scarce and expensive, then widen supply and compress margins as the fleet matures. But "soon" is not a plan — the honest approach is to avoid long commitments at today's rates (month-to-month or day-pass structures) so a price decline becomes savings instead of a contract you are locked out of.
Is 32 GB enough for AI workloads in 2026?
For the open-weights ecosystem as of October 2026, yes for most serving and fine-tuning work below frontier scale: the 8B–32B classes that dominate self-hosted deployments fit with headroom, and the 32B-at-4-bit tier — the current sweet spot for quality per gigabyte — is precisely the class the card was built to hold. The honest boundary is 70B-class at comfortable precision and long-context vision models at 262K-class contexts, both of which want more than any consumer card offers.